VESSL AI Powers Global Inference Service for Upstage’s Solar Pro 4, Backing Its No. 3 Usage Ranking on OpenRouter
SEOUL, SOUTH KOREA, October 13, 2026 /EINPresswire.com/ -- VESSL AI, a neocloud company led by CEO Jaeman An, announced

Press Release Disclaimer: This is a press release distributed through the XPR Media network. It has not been independently verified by our newsroom.
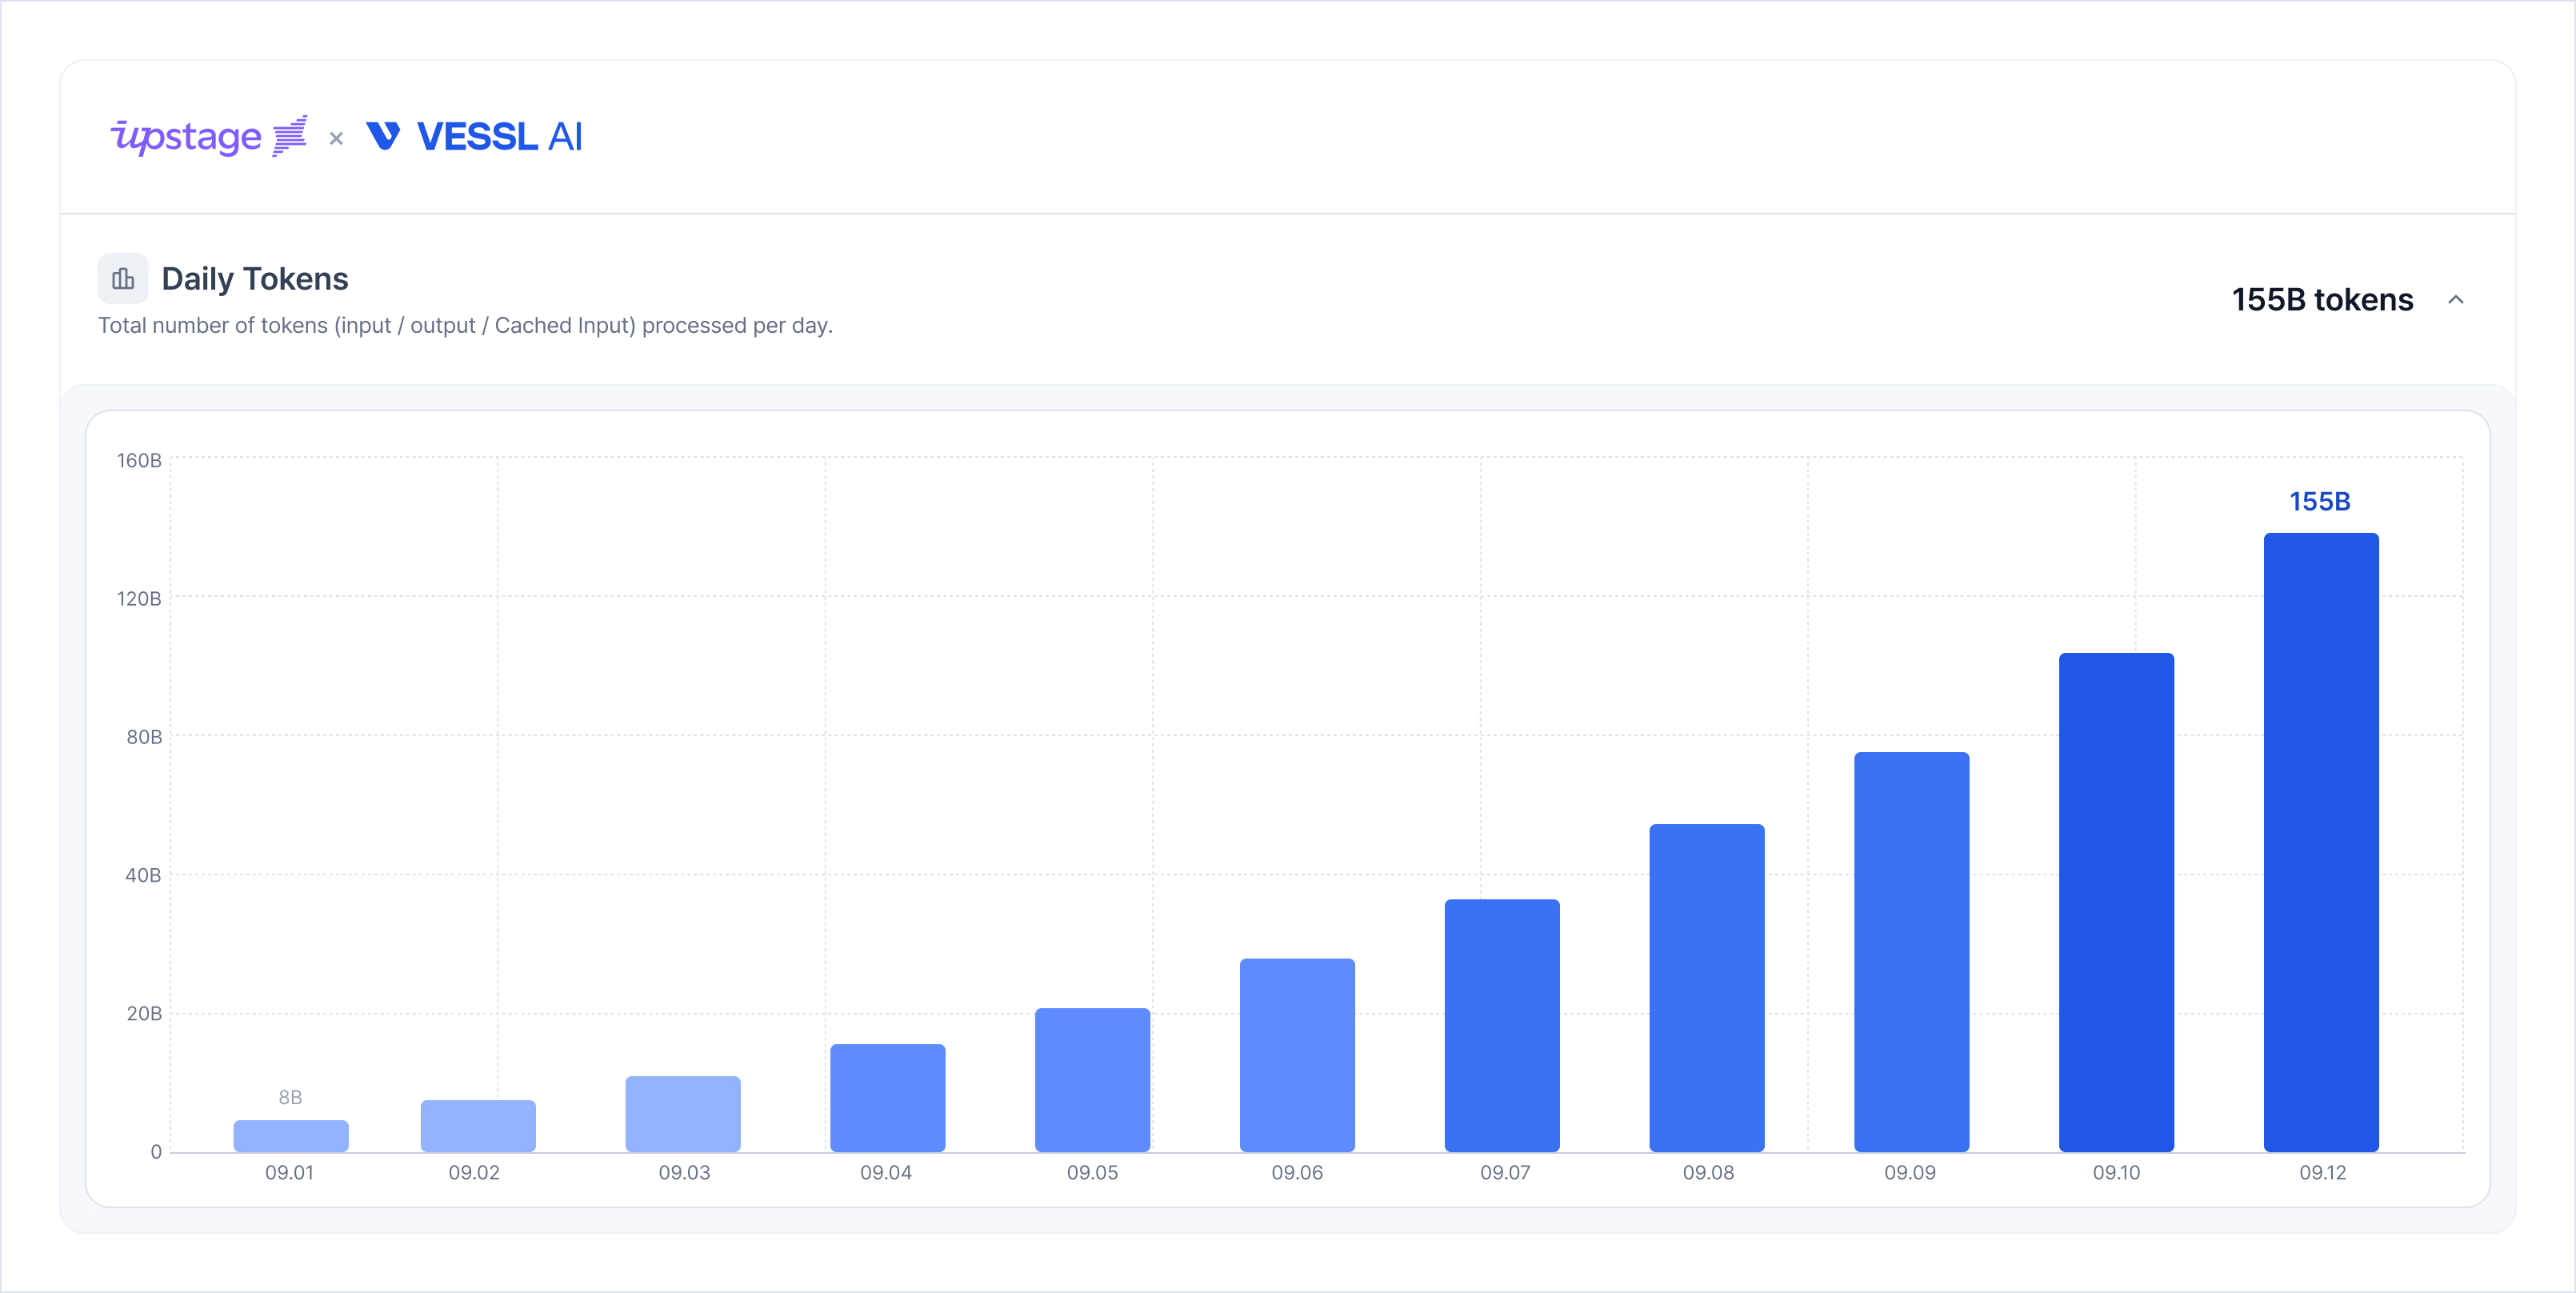

SEOUL, SOUTH KOREA, October 13, 2026 /EINPresswire.com/ — VESSL AI, a neocloud company led by CEO Jaeman An, announced that it provided global inference infrastructure for Upstage’s large language model (LLM), Solar Pro 4. VESSL AI applied its own optimization technology to speed up processing and cut costs, supporting Solar Pro 4’s global service operations.
In September this year, Solar Pro 4 ranked third by usage on OpenRouter, a global LLM marketplace. The ranking reflects actual usage tracked on the platform. During that period, VESSL AI managed Solar Pro 4’s global inference operations and processed inference requests from users worldwide. This case shows a Korean neocloud’s infrastructure helping a Korean-developed AI model expand its reach in global markets.
For interest in a model to turn into real service usage, the growing volume of requests must be handled reliably. That job falls to inference: the process of running a trained model in a live service environment so it can respond to user requests. Requests can spike in a short period, especially around new model launches and promotions, so it’s critical to secure enough processing capacity in advance to match expected demand.
To prepare for this, VESSL AI and Upstage shared launch and promotion schedules and expected demand, and designed the required inference capacity together. This was made possible by GPU clusters across multiple regions, including Korea, Europe, and the US, along with VESSL AI’s technology for optimizing its in-house inference engine. VESSL AI configured GPU resources and optimized its serving infrastructure to fit Solar Pro 4’s characteristics and real traffic patterns, raising throughput while lowering cost per token.
VESSL AI improved internal cache hit rates and applied techniques such as model quantization and KV cache-aware routing. With these optimizations, processing was twice as fast on average and up to three times as fast as before VESSL AI’s endpoint was introduced. The company also cut the cost per token by up to 50% through improvements in cache hit rates.
VESSL AI’s management of capacity planning and inference operations allowed Upstage to focus on model development and service expansion. The two companies plan to continue working together as adoption of the Solar models grows.
“This partnership is significant because the global success of a model developed in Korea was powered by a Korean neocloud’s infrastructure,” said Jaeman An, CEO of VESSL AI. “Building on our inference operations experience, we will strengthen our role as an inference provider, so model providers can focus on research and product development and enterprises can adopt open-source models reliably.”
VESSL AI continues to grow its enterprise customer base and infrastructure footprint. It recently supplied GPU compute power for AI R&D to SK Biopharmaceuticals and signed an MoU with NeoAI to build and operate a GPU cluster at the Pohang AI Data Center. With its experience serving Solar Pro 4 globally, VESSL AI is now expanding beyond GPU provisioning into inference operations for AI models.
Team Cookie Official
Team Cookie
+82 10-9274-5094
Visit us on social media:
LinkedIn
Facebook
Legal Disclaimer:
EIN Presswire provides this news content “as is” without warranty of any kind. We do not accept any responsibility or liability
for the accuracy, content, images, videos, licenses, completeness, legality, or reliability of the information contained in this
article. If you have any complaints or copyright issues related to this article, kindly contact the author above.

Media gallery